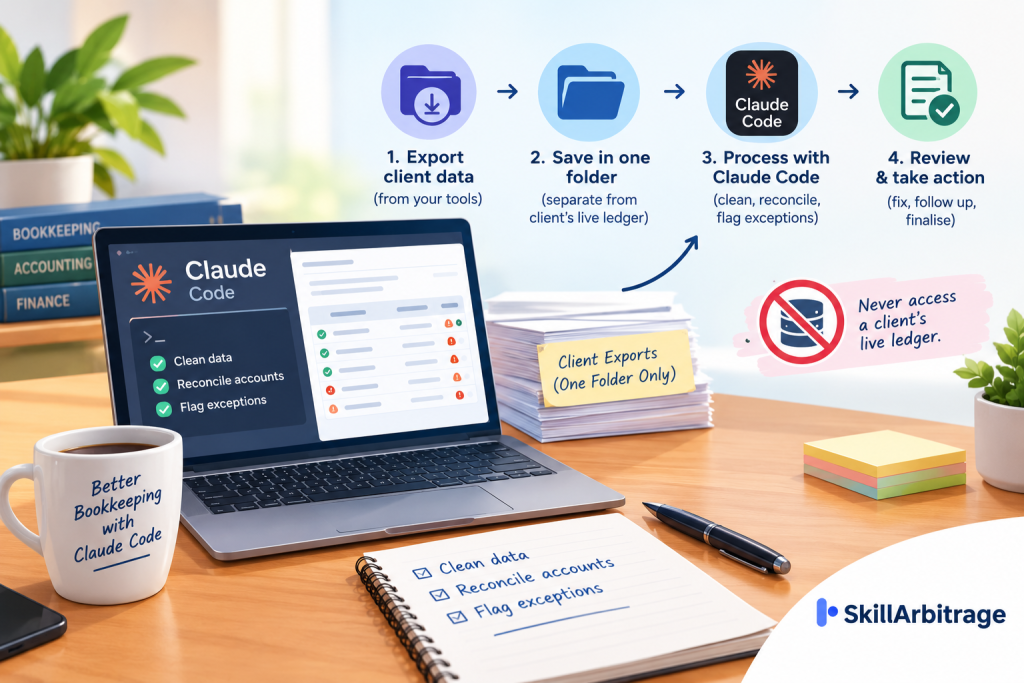

Claude Code starts with zero connections to your client’s books. It works on the files in one folder on your computer, so using Claude Code in a bookkeeping workflow means pointing it at exports you saved there yourself. It cleans them, reconciles them and flags exceptions. On its own, it posts nothing.
Anthropic’s own description of the tool calls it an agentic coding tool that reads files, edits them and runs commands, and it lists a terminal, a code editor, a desktop app and a browser as the places it runs. Agentic just means it works through a job in steps instead of answering one question and stopping. You don’t need to read or write code to use it, and that isn’t a sales line: Anthropic’s published report on how its own teams use it describes finance colleagues with no coding experience writing their data workflows into plain text files, loading those files in, and having the whole workflow execute, including being asked for the inputs it needed, such as dates. The stated result was that finance teams with no coding experience can now execute complex data workflows independently.
A terminal, since the word is about to keep coming up, is a window where you type an instruction instead of clicking a button. It’s the surface every tutorial assumes, and it isn’t the only door: the desktop app includes Claude Code, so the command-line version doesn’t have to be installed separately (which is the bit most write-ups skip past), and there’s a browser version as well. If you’ve never opened a terminal in your life, the desktop app is where to start. All of this is written for a bookkeeper who handles QuickBooks Online and Xero exports for US clients and has never written a line of code, the same reader who already knows that doing US bookkeeping without being tech-savvy is a question of method rather than software.
What Claude Code does in a bookkeeping workflow
Claude Code does its work on copies, on files you have already saved into one folder on your own computer, so every job in this section happens on an export and never inside a client’s live ledger. Anthropic’s permissions page states the rule plainly: by default, Claude has access to files in the directory where you launched it. A directory is a folder, and the folder it can see is the one you were sitting in when you started the tool. That sentence is most of the security model.
It’s also why this is not the chat window. In chat you paste the statement in, and the numbers leave your screen every time you want an answer about them. Here the file stays where it is and the tool reads it there. Automation reached bookkeeping in layers (bank feeds and rules inside the software, then document capture, then vendor-suggested coding, then chatbots used by pasting), each layer pushing the bookkeeper further from data entry and closer to review.
But the paste layer created a confidentiality problem it never solved. A tool that reads a file you cleaned yourself is a different shape of answer. So what can it actually touch? The graphic below maps it out.

Cleaning up the files you start with
The first job worth giving Claude Code is the one you already do by hand, which is turning a raw export into a file you can work with. A CSV, which is what the export button in QuickBooks Online or Xero hands you, is a plain text spreadsheet: rows of values with commas between them, readable by almost anything. Claude Code opens that file where it sits in the folder, splits merged fields, fixes date formats and sorts out the sign on credits and debits, then writes the result as a new file.
Reading inside the folder happens without asking you. Writing a file has to clear a permission check first. Here’s the thing about that split: the half of the job that can change something is the half that gets checked, and who does that checking depends on the mode you’re in.
Here’s what that actually looks like as an instruction: “Open bank-jan.csv, split the description column into payee and reference, put every date into YYYY-MM-DD form, and save the result as bank-jan-clean.csv.” That is the whole prompt. No code, no settings, no syntax to memorise.
Vendor names are the other obvious candidate. A month of card transactions arrives carrying hundreds of raw description strings for maybe forty real suppliers (the true count is almost always lower than the mess suggests), and it can map those strings to clean payee names and hand you the mapping as a file. You review the map before anything is applied anywhere, which means checking forty decisions rather than three hundred lines.
A folder of receipt and invoice PDFs is the same job wearing a different coat. It can rename each document by date and vendor and sort them into folders, and it can read that same folder and produce one file carrying date, vendor, amount and tax for every document in it. That second output is the one that saves an afternoon, because it turns a pile of paper into something you can sort and total.
Think of it this way. If you’re in Pune closing December for a client in Ohio, the useful version of that work isn’t a tidier folder. It’s one file you can open at 9pm, read down in five minutes, and turn into three questions for the client’s inbox before they wake up.
Now the part worth understanding rather than memorising. Tell it to save the result as a new file rather than change the one you downloaded, the way that example instruction does. The export stays the export, and a cleaned version that came out wrong gets deleted and redone. That is the reason to work on exports in the first place, and it’s why the write step going through a check is a feature rather than friction.
One thing about scans before you start, because the warning you’ll read elsewhere is out of date. It reads a photographed or scanned receipt directly, as a picture it can look at rather than as raw bytes, so you don’t have to turn it into text first. What it does do is shrink a large image before looking at it, which is where fine detail gets lost, so crop the part you care about when a figure sits small on the page. Long PDFs it reads in page ranges rather than in one go.
Finding the exceptions in a month of transactions
Point Claude Code at two exported files and it’ll tell you what doesn’t match, and point it at a set of rules you wrote in plain English and it’ll tell you which lines break them. Both jobs end in the same place: a short list of things that need a human decision. That list is the actual deliverable, which is why the two belong together rather than apart.
Reconciliation first. You export the bank statement as one file and the ledger as another, drop both into the client folder, and ask for the comparison. What comes back is three lists, plus duplicates: lines that matched, lines in the bank that aren’t in the ledger, and lines in the ledger that aren’t in the bank.
The instruction is as plain as it sounds: “Compare bank-jan-clean.csv with ledger-jan.csv on date and amount, and give me three lists: matched, in the bank but not in the ledger, and in the ledger but not in the bank.” If you’ve never worked the manual version end to end, how a bank reconciliation is actually worked through is worth reading alongside this, because the tool accelerates a method you still have to understand well enough to check.
The client’s live ledger is never touched by any of this. Nothing is connected to QuickBooks Online or to Xero. Two files sit in a folder and get compared, and if you deleted both of them right now the client’s books would be exactly as they were this morning. That is worth saying twice, because the fear people arrive with is that an AI tool is quietly editing something, and here there is nothing to edit.
Rule checking is the same move applied to categorisation. You write your rules as sentences, in the words you’d use to explain them to a new assistant, and it flags the lines that break them. The output is an exception list, not a posting, and that distinction is the difference between a helpful first pass and a tool making decisions in your name.
A rule set reads like this: “Anything from a fuel retailer goes to Auto Expense, anything under five dollars from a coffee shop goes to Meals, and flag every payment over two thousand dollars with no matching invoice in the receipts folder.” Written once, applied to a whole month, returned as exceptions you decide on.
Fair warning on the arithmetic. Check the figures yourself before they go anywhere near a client, because an exception list is a starting point and not a verdict. Anthropic’s security guidance is blunt about where responsibility sits: you are responsible for reviewing what it proposes before you approve it. The practical reality is that this is a first-pass tool, and the first pass is the part that used to eat a whole Tuesday.
The question bookkeepers raise first is whether the exception list can be trusted enough to act on without also checking the matched lines. Our recommendation is to spot-check the matches for the first two or three months, because what you’re really testing in that period is whether your export is shaped the way you assume it is. In practice, though, once you know the file the checking drops off on its own.
Getting the same job to run again next month
The gain that matters with Claude Code isn’t the first run. It’s that you can write the job down once and have it run the same way in January, February and March without explaining it again from scratch.
That is precisely what Anthropic’s finance team did, which is why it’s the strongest evidence on this page. The report describes colleagues with no coding experience writing plain text files that said things like query this dashboard, get information, run these queries, produce Excel output, then loading the file and having the entire workflow execute, with the tool asking for inputs such as dates along the way. The stated impact: finance teams with no coding experience can now execute complex data workflows independently. Nothing in that sentence is about programming.
There’s a second version of the same idea, and it’s the bigger gain over a chat window. It can write a small script for you, a script being a list of instructions saved in a file that a computer runs the same way every time (you never have to read it, only approve it). Once the repeatable part of a job lives in a script, it stops being worked out afresh each month and starts simply being run.
Two files are worth knowing by name. A CLAUDE.md is a plain text file you keep in the client’s folder, which the tool reads at the start of every session, and it holds facts about that client. A skill file holds a procedure rather than facts, and you call it by name when you want it. In bookkeeping terms the split is easy: your client’s conventions are facts, and your close checklist is a procedure.
A CLAUDE.md line looks like this: “This client’s financial year ends 31 December. Owner draws code to Owner Distributions, never to Payroll.” A skill is a file named something like month-end-close, whose steps are written as ordinary sentences, so your month-end close steps become something you invoke by name instead of re-typing.
And it drafts the documents themselves too: the close SOP, the onboarding checklist, the handover note for whoever covers you in December, and a P&L narrative or a client email built from figures you supply.
How far does this go? A practitioner published a fifteen-part playbook running real books this way, on a plain-text double-entry ledger with scripted bank feeds and a strict reconciliation loop, governed by one rule: scripts fetch, Claude proposes, the owner approves, then Claude records. That is well past where a non-technical bookkeeper starts. Read it as the shape of the thing rather than the starting point.
There’s a knock-on effect here that’s worth more than the time saved. Because the output is a rule set, an exception list or a script rather than a chat answer, what you hand the client changes from “I categorised these” to “here is the rule set, here is what broke it, here is what I decided”. And that is the honest argument for why this makes a bookkeeper more valuable rather than less.
Where Claude Code stops in a bookkeeping workflow
Claude Code stops at the client’s live ledger, because out of the box it has no connection to one at all.
Claude Code does not connect to QuickBooks Online or Xero by default. Intuit publishes an official QuickBooks Online server and Xero publishes one of its own, so a connection is possible. Setting one up means registering a developer app and holding OAuth credentials for a client’s live books on your own machine, which is a decision about data access rather than a setting you flip.
Both of those run through the Model Context Protocol, an open standard for plugging an AI tool into another system, where the plug has to be installed and authorised by you. OAuth, while the acronym is here, is the sign-in handshake that lets one piece of software act on your account inside another without ever being given your password. Intuit’s official QuickBooks Online server runs locally on your own machine and needs an app registered on Intuit’s developer portal, and Xero publishes one too, authenticated with a Custom Connection or a bearer token.
So it can be given a connection. It does not come with one, and giving it one is a data-access decision that belongs in the engagement letter rather than in a tutorial (which makes it a conversation with the client, not a setting). Anthropic tells you to verify that you trust each server before connecting it, and says plainly that it does not security-audit the servers listed in its own directory.
The rest of the boundary is shorter than people expect. There’s no live bank feed and no account balance: it sees the export you saved, as at the moment you saved it. It files nothing with any authority, anywhere.
The conversation itself doesn’t carry from one session into the next. Continuity comes from files instead: the CLAUDE.md you write, plus a memory file it builds for itself as it works. The documentation describes no audit trail feature, so any record of who changed what and when is one you build by saving your own outputs. And it is no substitute for professional judgement on revenue recognition, payroll tax positions or a year-end sign-off.
This is also the line between two things that both get called AI in accounting. The AI built into QuickBooks and Xero themselves sits inside the software and already has the ledger. Claude Code sits on your machine and has a folder. Neither one is the other.
Both official connectors already exist and already run locally with an OAuth handshake, which tells you something about where this is heading. But the remaining barrier isn’t whether the software can reach a ledger. It’s who is allowed to hold a client’s credentials, which is governance rather than capability.
There’s no worked example in this section, deliberately. A prompt can’t cross this boundary, and writing one out would imply a clever instruction could. Anthropic’s own framing is the same here as everywhere else: it only has the permissions you grant it, and you remain responsible for reviewing what it proposes.
Running Claude Code on client files
Running it on client files comes down to four decisions you make before it reads anything, and all four are yours rather than the tool’s. None of them is technical. So what is there to decide?
The first is the plan, because Claude Code isn’t sold on its own. It comes with Pro, Max, Team and Enterprise.
Claude Code isn’t available on the free tier. For one person, Pro is the entry point at $17 a month on the annual plan or $20 billed monthly, and there’s no charge per reconciliation on a subscription. What you get instead of a price per job is a usage limit: the documentation describes a session limit and a weekly one on a subscription plan, and a heavy day can reach them.
That ceiling, rather than the price, is the one people actually meet. Budget for a session here eating more of the allowance than a chat session does, since every turn carries file contents and several steps. The current plan pricing and how the usage allowance works are both published.
Second is the door. The desktop app is the gentler one and needs no separate install (it’s the honest answer for a first-time user). If you’d rather have the terminal, the install is a single line on Windows and a single line on Mac, and Anthropic’s setup page carries the current one for each. Copy it from there rather than from any article, including this one, because an install command is exactly the sort of thing that changes quietly. You then move into the client’s folder and type claude to start a session there.
Third is the folder, and this is the actual control rather than a tidiness preference. Make one folder per client, holding that client’s exports and nothing else, then move into it and start the tool there, because the folder you start in is the boundary of what it can see. Extra folders get added one at a time and on purpose. Never start it in a parent folder holding all your clients, or in your home directory, because then the boundary is everything you own.
Worth flagging if you work off a client’s network drive: most network paths, the ones written with two backslashes and a server name, can’t be used as a working directory on Windows. Map the share to a drive letter and add that deliberately instead.
Fourth is redaction, and this is where the file beats the chat window outright. Strip the identifiers out of the export before it goes into the folder: account numbers, tax identification numbers, anything naming a person rather than a transaction. You do that once, in the file, and every session afterwards inherits it.
Pasting into a chat window re-exposes the full statement every single time you ask about it. Bottom line: you redact once, not once per question.
What leaves your machine, and what stays on it
Your prompts and the model’s replies leave your machine over an encrypted connection, file contents leave only when the tool reads a file into a prompt, and everything else stays put unless you choose to send it.
What Anthropic says it does with the data comes down to four short answers. Prompts and outputs go to Anthropic, encrypted in transit (that part is unavoidable, since the model doesn’t live on your laptop). Telemetry, which is the usage data the software reports back about itself, carries no prompts, no code and no file paths. Feedback and session-survey transcripts leave only when you explicitly say yes.
Then there’s the decision most readers don’t know they’re making. On Free, Pro and Max, Anthropic trains new models on your data when the setting is on, and that setting sits in your privacy controls. Under commercial terms, which cover Team, Enterprise and the API, it does not train on what is sent to Claude Code.
Retention follows the same split, as figures: five years with the training setting on, thirty days with it off, thirty days as standard on commercial terms. Zero data retention does exist, but only for qualified Enterprise accounts, and it isn’t part of the standard plan.
And here’s the one almost nobody writes about. Session transcripts are stored on your own machine, in plain text, inside a Claude folder in your user profile, for thirty days by default, and that period is adjustable. Sessions you ran in the desktop app sit outside that clean-up by default, so they aren’t on a thirty-day clock at all. On a bookkeeper’s laptop that is a second copy of client figures living outside the client folder, and the right response is a file-hygiene habit rather than alarm: two places to think about instead of one.
None of this obligation is created by the tool. It’s created by client financial data sitting on your machine, and a bookkeeper serving US clients is already carrying the consent and safeguarding rules that already apply to client financial data. What genuinely changes is narrow: your plan tier now decides whether your prompts train a model and whether retention runs thirty days or five years, and a plaintext transcript now persists locally for a month.
What it asks you before it changes anything
Claude Code asks before it edits a file, before it runs a command and before it reads anything outside the folder you started it in. But it only asks in the mode that does that, and on a paid plan that is not the mode you start in.
In Manual mode, Claude Code prompts you before editing a file, running a shell command, fetching a web page, or reading anything outside the folder it started in. Reads inside that folder are unprompted. On Pro, Max and Team, the mode the session starts in is auto mode, where a classifier checks actions against your request rather than you. Seeing every action is a switch you make.
A permission mode is simply how much the tool checks with you before it acts. Most write-ups on this topic reassure you that it always asks first. But on a standard paid plan, out of the box, it doesn’t.
One setting fences it to your folder in every mode, and it has a thoroughly unlovely name: blockReadsOutsideWorkingDirectories (you only ever type it once). Switch it on and the file tools refuse any path outside the folders you’ve allowed, whatever mode the session is in. On a machine holding client files, that’s the switch to know about.
Two more things about the controls, both short. Deny beats ask, which beats allow, and an allow rule can’t carve an exception out of a deny rule. And the rules are enforced by the program itself rather than by the model, so an instruction you write into a CLAUDE.md shapes what it tries to do but never changes what it is permitted to do.
One mode never belongs on a machine holding client files, and that’s the one that skips permission prompts altogether. Anthropic restricts it to isolated containers and virtual machines.
One more habit worth building, and it comes out of how the modes actually behave. Deny rules hold in every mode, including the one that skips prompts, so a folder you have blocked stays blocked whatever mode you drift into. And in auto mode, the first time it reads a file outside your working folder it stops and asks whether to keep allowing reads like that, which is the moment to say no rather than to wave it through.
Anthropic’s security guidance puts the whole question in two sentences: “Claude Code only has the permissions you grant it. You’re responsible for reviewing proposed code and commands for safety before approval.”
FAQs
What is the difference between Claude Code and Claude Cowork?
Cowork takes a goal and works across the files and tools you choose, then delivers work for you to review. The Cowork product page says it needs a paid plan, has a Cowork desktop app of its own, and is rolling out on web and on mobile in beta. Claude Code is the agent you run yourself, in a folder, from a terminal or the desktop app. Same family, different handle: one is steered by the goal you set, the other by the session you’re sitting in.
Should you use Claude Code or paste into Claude chat instead?
The deciding factor is where the data sits. Pasting means the full statement leaves your screen every time you want an answer about it, and a redaction you made last month doesn’t carry forward into next month’s question. A file you redacted once stays redacted for every session after it. Chat also can’t repeat a job the same way twice without you re-typing the instructions, which is the other half of the gain.
Is my Claude login safe on the machine that holds client files?
The credential sits in a file inside your Windows user profile folder and inherits that folder’s access controls, which is what the documentation on where the credential is stored sets out. Its safety is therefore the safety of your Windows account, no more and no less. A shared laptop, or one left unlocked on a desk, is the exposure here rather than the tool.
Disclaimer
This article is for educational purposes only and does not constitute professional, financial, legal, or immigration advice. For guidance specific to your situation, consult a qualified professional.


 Allow notifications